Métricas de agentes de IA: medir casos resueltosAI Agent Metrics: Measuring Resolved Cases
El costo por respuesta ayuda a controlar gasto, pero no dice si el agente resolvió el trabajo correcto ni qué casos dejó atrás.Cost per response helps control spending, but it doesn't indicate whether the agent resolved the right work or what cases were left behind.
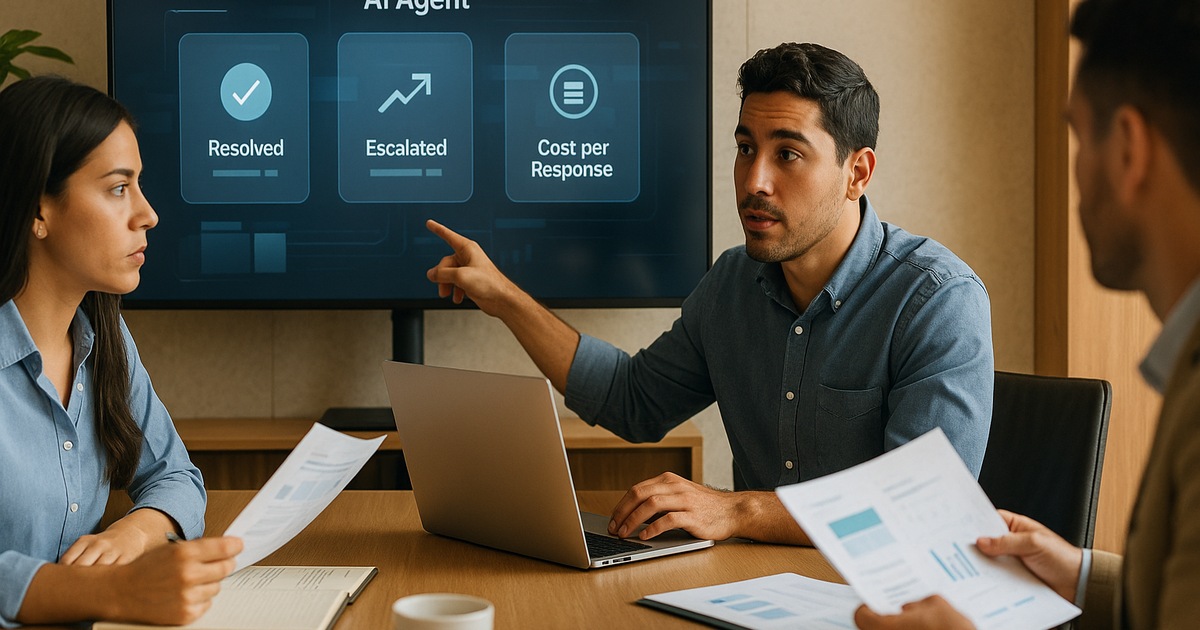
El costo por respuesta no cuenta toda la historia
Medir un agente de IA por costo por respuesta parece razonable. La cifra es clara, baja a una hoja de cálculo y ayuda a vigilar consumo. Si cada interacción cuesta menos que una atención humana, el proyecto aparenta avanzar bien.
El problema es que una respuesta barata puede no haber resuelto nada. Puede haber contestado una parte, haber confundido el caso, haber empujado al usuario hacia otro canal o haber dejado una excepción sin dueño. En soporte, ventas, admisión, compras o gestión interna, lo que importa no es cuántas veces habló el agente, sino qué trabajo quedó cerrado con evidencia suficiente.
Por eso una implementación de IA aplicada necesita mirar el caso completo. La respuesta es apenas una pieza. El valor aparece cuando el agente reduce espera, ordena información, evita retrabajo y escala a tiempo lo que no debe resolver solo.
Una conversación no siempre equivale a un caso
Un mismo caso puede tener cinco mensajes. O cinco casos distintos pueden llegar mezclados en una sola conversación. Si la métrica solo cuenta respuestas, el tablero se vuelve cómodo pero engañoso. El agente puede verse productivo porque habló mucho, mientras el equipo sigue resolviendo a mano lo importante.
Antes de medir, conviene definir qué es un caso para esa operación. En atención al cliente puede ser una solicitud con motivo, identidad, estado y cierre. En ventas, una oportunidad con próximo paso claro. En soporte interno, un ticket con categoría, prioridad, responsable y resultado. En administración, un trámite con documentos, aprobación o faltante identificado.
La unidad de medida debe parecerse al trabajo real. Si no, la empresa termina optimizando frases, no operación.
Casos resueltos, escalados y abandonados
Una métrica más útil separa tres grupos. Casos que el agente resolvió dentro de su alcance. Casos que escaló con buen contexto. Casos que quedaron abandonados, repetidos o devueltos al equipo sin información suficiente.
El primer grupo muestra eficiencia real. El segundo también puede ser un éxito, aunque no parezca tan vistoso. Un agente que detecta una excepción, resume evidencia y entrega el caso a la persona correcta está haciendo buen trabajo. Lo peligroso es medirlo como fracaso solo porque no cerró la conversación automáticamente.
El tercer grupo suele esconder el costo verdadero. Ahí están los usuarios que repiten datos, los agentes humanos que deben reconstruir la historia, los reclamos que reaparecen y los casos que nadie sabe si siguen abiertos. Ese costo no siempre aparece en la factura del modelo, pero sí aparece en la operación.
La calidad necesita consecuencias, no estrellas
Pedirle al usuario que califique la respuesta con una estrella puede aportar señales, pero no basta. Hay respuestas educadas que no resolvieron el problema. También hay respuestas secas que hicieron exactamente lo necesario. En una empresa, la calidad debe medirse por consecuencia.
¿El cliente tuvo que volver a escribir? ¿El caso cambió de estado correctamente? ¿La persona que recibió el escalamiento entendió qué hacer? ¿La información usada estaba vigente? ¿El agente evitó prometer algo que no podía confirmar? Esas preguntas pesan más que una nota promedio.
La automatización de procesos funciona mejor cuando cada salida deja rastro. Si el agente clasifica, debe quedar la clasificación. Si prepara un borrador, deben verse las fuentes. Si escala, debe conservar contexto. Si se equivoca, el error debe servir para ajustar el proceso y no solo para corregir una frase.
El tablero debe mostrar dónde trabaja el humano
Un agente de IA no elimina todo el trabajo humano. Lo cambia de lugar. A veces reduce preguntas repetidas, pero aumenta revisión de excepciones. A veces acelera clasificación, pero revela que los formularios llegan incompletos. A veces responde mejor que el equipo en temas simples, pero deja más visibles los casos donde falta política interna.
El tablero debería mostrar esa redistribución. Cuánto tiempo se ahorra en consultas repetidas. Cuántos casos llegan mejor preparados. Cuántas revisiones humanas siguen siendo necesarias. Cuántas correcciones nacen de datos mal capturados, fuentes vencidas o permisos mal definidos.
Esa lectura evita una discusión falsa: humano contra agente. La pregunta útil es otra: qué parte del trabajo quedó más clara y qué parte sigue necesitando criterio, autoridad o rediseño.
Las excepciones valen más que el promedio
Los promedios tranquilizan demasiado. Tiempo medio de respuesta, costo promedio por interacción, porcentaje de automatización. Sirven para mirar tendencia, pero pueden ocultar los casos que duelen.
Una empresa debería revisar las excepciones con especial atención. Casos que el agente tardó demasiado en escalar. Solicitudes que cambiaron de tema. Usuarios que enviaron información contradictoria. Respuestas que citaron una fuente correcta pero incompleta. Procesos donde el agente dependía de un dato que el sistema nunca tenía actualizado.
Ahí aparece la mejora de verdad. No en celebrar que el agente contestó miles de veces, sino en descubrir qué tipo de caso rompe el flujo y qué cambio lo haría más confiable.
Medir bien también protege el presupuesto
Controlar consumo sigue siendo importante. El costo por respuesta ayuda a evitar sorpresas, comparar modelos, revisar volumen y detectar conversaciones que se alargan sin motivo. Solo que debe ocupar su lugar correcto: es una métrica financiera, no una prueba de valor.
Para decidir si el agente merece seguir creciendo, conviene cruzar costo con resultado. Cuánto cuesta resolver un caso simple. Cuánto cuesta preparar un escalamiento útil. Cuánto cuesta detectar una excepción antes de que llegue tarde. Cuánto retrabajo se evita cuando el agente consulta una fuente vigente.
La operación y soporte digital necesita ese equilibrio. Si el agente es barato pero obliga al equipo a revisar todo, el ahorro es aparente. Si cuesta más por interacción pero reduce errores, tiempos muertos y casos repetidos, puede ser una mejor decisión.
Una buena métrica cambia el diseño del agente
Las métricas no deberían aparecer al final como reporte decorativo. Deben influir en el diseño. Si se medirá resolución, el agente necesita saber cuándo un caso está cerrado. Si se medirá escalamiento, debe capturar motivo, evidencia y responsable. Si se medirá retrabajo, debe registrar cuándo el usuario vuelve por el mismo asunto.
El primer tablero puede ser simple: casos recibidos, resueltos por el agente, escalados con contexto, devueltos por falta de información, corregidos por el equipo y reabiertos. Con eso ya se puede tener una conversación honesta sobre valor.
Un agente de IA empieza a madurar cuando la empresa deja de preguntar solamente cuánto cuesta cada respuesta. La pregunta más útil es qué pasó con el caso después de la respuesta. Si nadie puede contestar eso, todavía no hay medición operativa. Hay actividad, gasto y una ilusión de productividad.
Cost per Response Doesn’t Tell the Whole Story
Measuring an AI agent by cost per response seems reasonable. The figure is clear, drops into a spreadsheet, and helps monitor consumption. If each interaction costs less than human assistance, the project appears to be progressing well.
The problem is that a cheap response may not have resolved anything. It might have answered part of the query, confused the case, pushed the user to another channel, or left an exception unaddressed. In support, sales, admissions, purchasing, or internal management, what matters is not how many times the agent spoke, but what work was closed with sufficient evidence.
That’s why an implementation of applied AI needs to look at the complete case. The response is just one piece. The value emerges when the agent reduces wait times, organizes information, avoids rework, and escalates in a timely manner what it shouldn’t resolve alone.
A Conversation Doesn’t Always Equal a Case
The same case can have five messages. Or five different cases can arrive mixed in a single conversation. If the metric only counts responses, the dashboard becomes comfortable but misleading. The agent may appear productive because it spoke a lot, while the team continues to handle the important resolutions manually.
Before measuring, it’s wise to define what constitutes a case for that operation. In customer service, it could be a request with a reason, identity, status, and closure. In sales, an opportunity with a clear next step. In internal support, a ticket with category, priority, responsible party, and outcome. In administration, a process with documents, approval, or identified missing items.
The unit of measurement should resemble the actual work. If not, the company ends up optimizing phrases, not operations.
Resolved, Escalated, and Abandoned Cases
A more useful metric separates three groups: cases that the agent resolved within its scope, cases that it escalated with good context, and cases that were abandoned, repeated, or returned to the team without sufficient information.
The first group shows real efficiency. The second can also be a success, even if it doesn’t seem as flashy. An agent that detects an exception, summarizes evidence, and hands the case to the right person is doing a good job. The danger lies in measuring it as a failure just because it didn’t close the conversation automatically.
The third group often hides the true cost. Here are the users who repeat data, the human agents who must reconstruct the story, the complaints that reappear, and the cases that no one knows if they are still open. That cost doesn’t always show up on the model’s invoice, but it does appear in operations.
Quality Needs Consequences, Not Stars
Asking the user to rate the response with a star can provide signals, but it’s not enough. There are polite responses that didn’t resolve the problem. There are also terse responses that did exactly what was necessary. In a company, quality should be measured by consequence.
Did the customer have to write back? Did the case change status correctly? Did the person who received the escalation understand what to do? Was the information used up to date? Did the agent avoid promising something it couldn’t confirm? These questions weigh more than an average score.
Process automation works better when each output leaves a trace. If the agent classifies, the classification should remain. If it prepares a draft, the sources should be visible. If it escalates, it should retain context. If it makes a mistake, the error should serve to adjust the process and not just to correct a phrase.
The Dashboard Should Show Where Humans Work
An AI agent doesn’t eliminate all human work. It shifts it around. Sometimes it reduces repeated questions, but increases the review of exceptions. Sometimes it speeds up classification, but reveals that forms arrive incomplete. Sometimes it responds better than the team on simple topics, but makes more visible the cases where internal policy is lacking.
The dashboard should show this redistribution. How much time is saved on repeated inquiries. How many cases arrive better prepared. How many human reviews are still necessary. How many corrections arise from poorly captured data, outdated sources, or poorly defined permissions.
This reading avoids a false discussion: human versus agent. The useful question is different: which part of the work became clearer and which part still needs judgment, authority, or redesign.
Exceptions Matter More Than Averages
Averages can be too reassuring. Average response time, average cost per interaction, percentage of automation. They serve to observe trends but can hide the cases that hurt.
A company should review exceptions with special attention. Cases where the agent took too long to escalate. Requests that changed topics. Users who sent contradictory information. Responses that cited a correct but incomplete source. Processes where the agent depended on data that the system never had updated.
That’s where real improvement appears. Not in celebrating that the agent answered thousands of times, but in discovering what type of case breaks the flow and what change would make it more reliable.
Measuring Well Also Protects the Budget
Controlling consumption remains important. Cost per response helps avoid surprises, compare models, review volume, and detect conversations that drag on unnecessarily. It just needs to occupy its correct place: it’s a financial metric, not a measure of value.
To decide if the agent deserves to continue growing, it’s wise to cross cost with outcome. How much does it cost to resolve a simple case? How much does it cost to prepare a useful escalation? How much does it cost to detect an exception before it’s too late? How much rework is avoided when the agent consults an up-to-date source?
Digital operation and support needs that balance. If the agent is cheap but forces the team to review everything, the savings are illusory. If it costs more per interaction but reduces errors, downtime, and repeated cases, it may be a better decision.
A Good Metric Changes the Agent’s Design
Metrics shouldn’t appear at the end as decorative reports. They should influence design. If resolution is to be measured, the agent needs to know when a case is closed. If escalation is to be measured, it must capture the reason, evidence, and responsible party. If rework is to be measured, it must record when the user returns for the same issue.
The first dashboard can be simple: cases received, resolved by the agent, escalated with context, returned for lack of information, corrected by the team, and reopened. With that, an honest conversation about value can already take place.
An AI agent begins to mature when the company stops asking only how much each response costs. The most useful question is what happened to the case after the response. If no one can answer that, there’s still no operational measurement. There’s activity, expenditure, and an illusion of productivity.
¡Gracias por tu opinión!
No se pudo registrar tu voto. Inténtalo de nuevo.
IA aplicadaApplied AI
Agentes, asistentes y automatización con fuentes confiables.Agents, assistants, and automation with reliable sources.
Automatización de procesosProcess Automation
Flujos, integraciones y reportes con control operativo.Workflows, integrations, and reports with operational control.
Operación, soporte y mantenimiento webWeb Operation, Support, and Maintenance
Continuidad, soporte y operación digital con seguimiento claro.Continuity, support, and digital operation with clear tracking.
¿Listo para aplicar esto en su operación?
Hagamos un diagnóstico inicial, sin compromiso.